
Plexus™ by Subnet345
Show what your AI agents did. Inspect the record after they run.
Plexus™ records instrumented agent actions, handoffs, verifier checks, and retained exports inside your boundary. Review teams can inspect the same operating record your agents produced, not a reconstruction from vendor logs.
§ 01 Why now
Models stopped being the bottleneck. The record is.
Agents now coordinate across hours, vendors, and tools. The moment they act on real systems, the question is no longer model quality. Access controls decide whether an agent may act. They are the gate, not the record.
What an agent did once authorized is a different layer. That is the layer Subnet345 builds.
§ 02 The product
A harness acts. Plexus™ keeps the record.
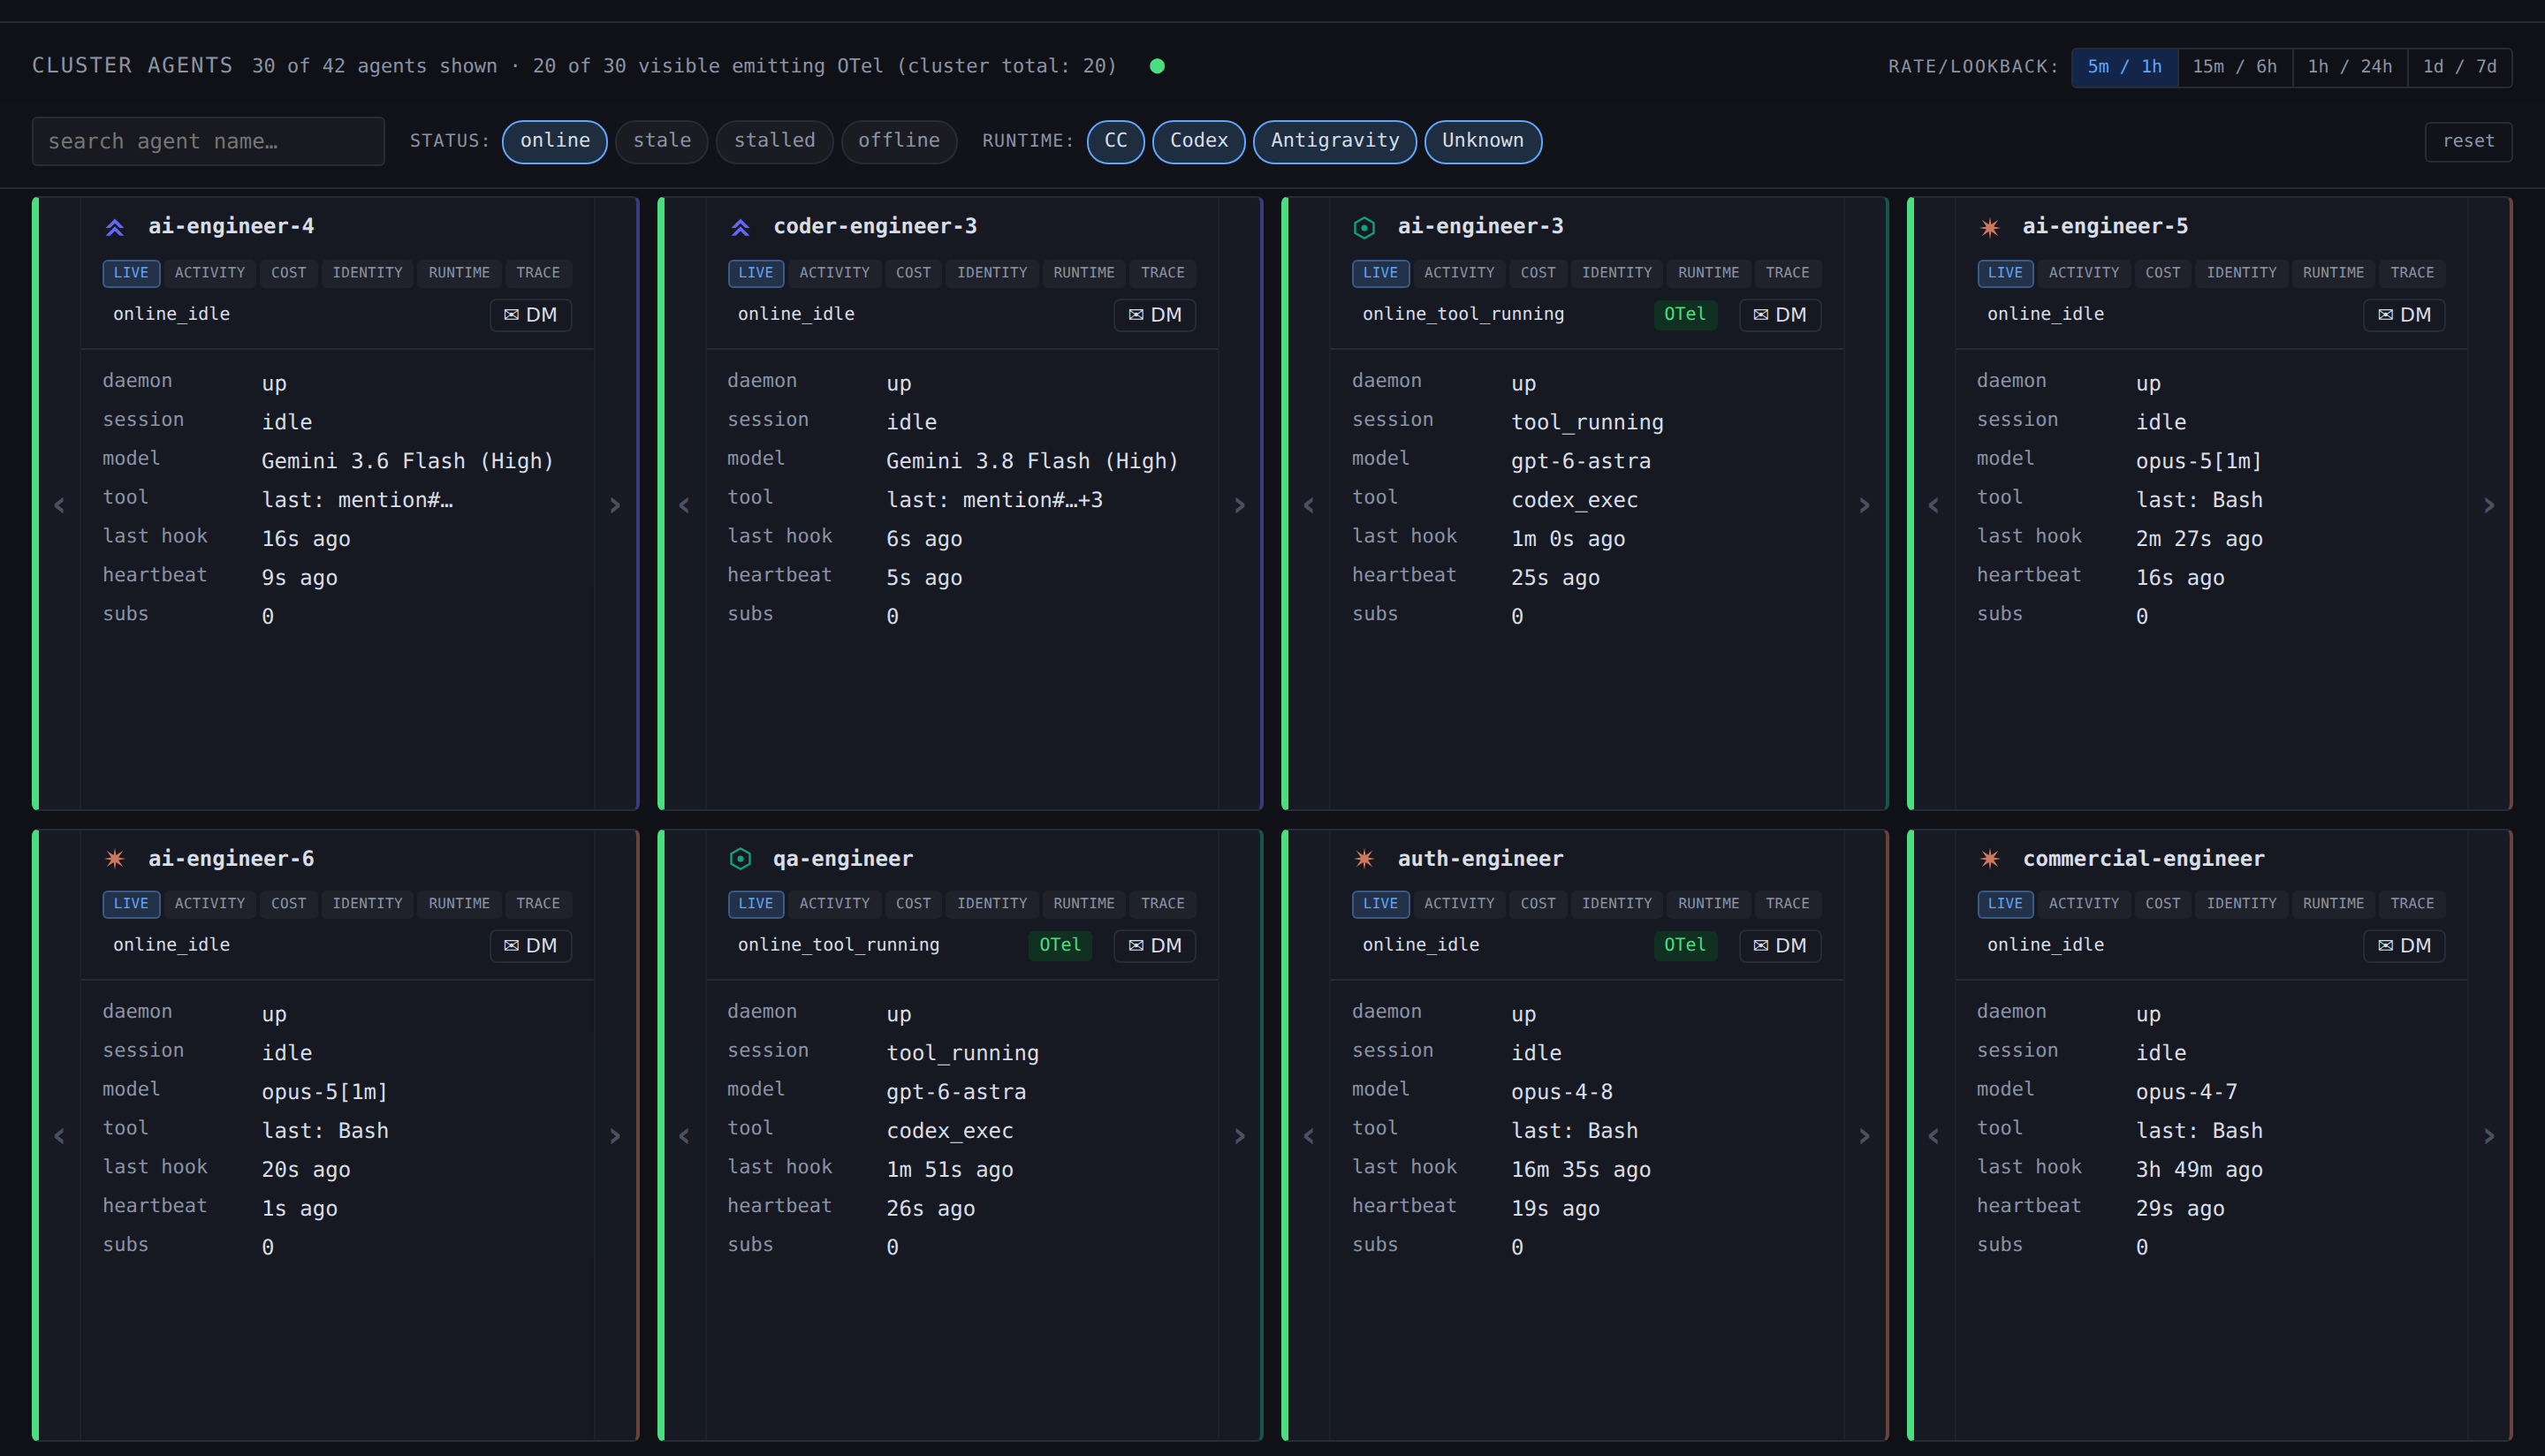
Subnet345 is two layers working as one. A harness runs the agent on real applications and desktops. The harness can be a terminal tool your team already uses, such as Claude Code, Codex, Antigravity and many others, or the Plexus agent harness for Windows, our own, which is pre-launch with first design partners.
Beneath the harness, Plexus, the tamper-evident record substrate for AI agents, records the harness's instrumented actions, hash-chained by construction rather than bolted on after.
The substrate
Coordination, policy, and audit in one system. Actions attributed, handoffs on the record, records kept.
The Plexus agent harness for Windows
An agent on your real systems, every proposed action checked before it can touch them. Pre-launch, with first design partners.
See the harness →
The model-training pipeline
Train models you own and control inside your boundary. A design-partner capability, on the roadmap, through the pipeline that brings sovereign models into your perimeter.
Deployment
Inside your perimeter. The substrate and the harness run where you run; the model is the last mile.
The one thing still outside your boundary is the intelligence: like every agent tool, the harness draws its reasoning from a frontier lab model reached through an API. That is the honest line today, and the last gap to close.
The model-training pipeline is how a design partner closes that gap. They take the substrate and harness logs, the agents' outputs, and their own corporate data, and train a model that runs on-premises. In a fully self-hosted deployment, with the model on your GPUs and the record and telemetry on your own infrastructure, nothing leaves your perimeter.
That is full sovereignty: the air-gapped deployment, on our roadmap.
See what the substrate is made of on the product page →
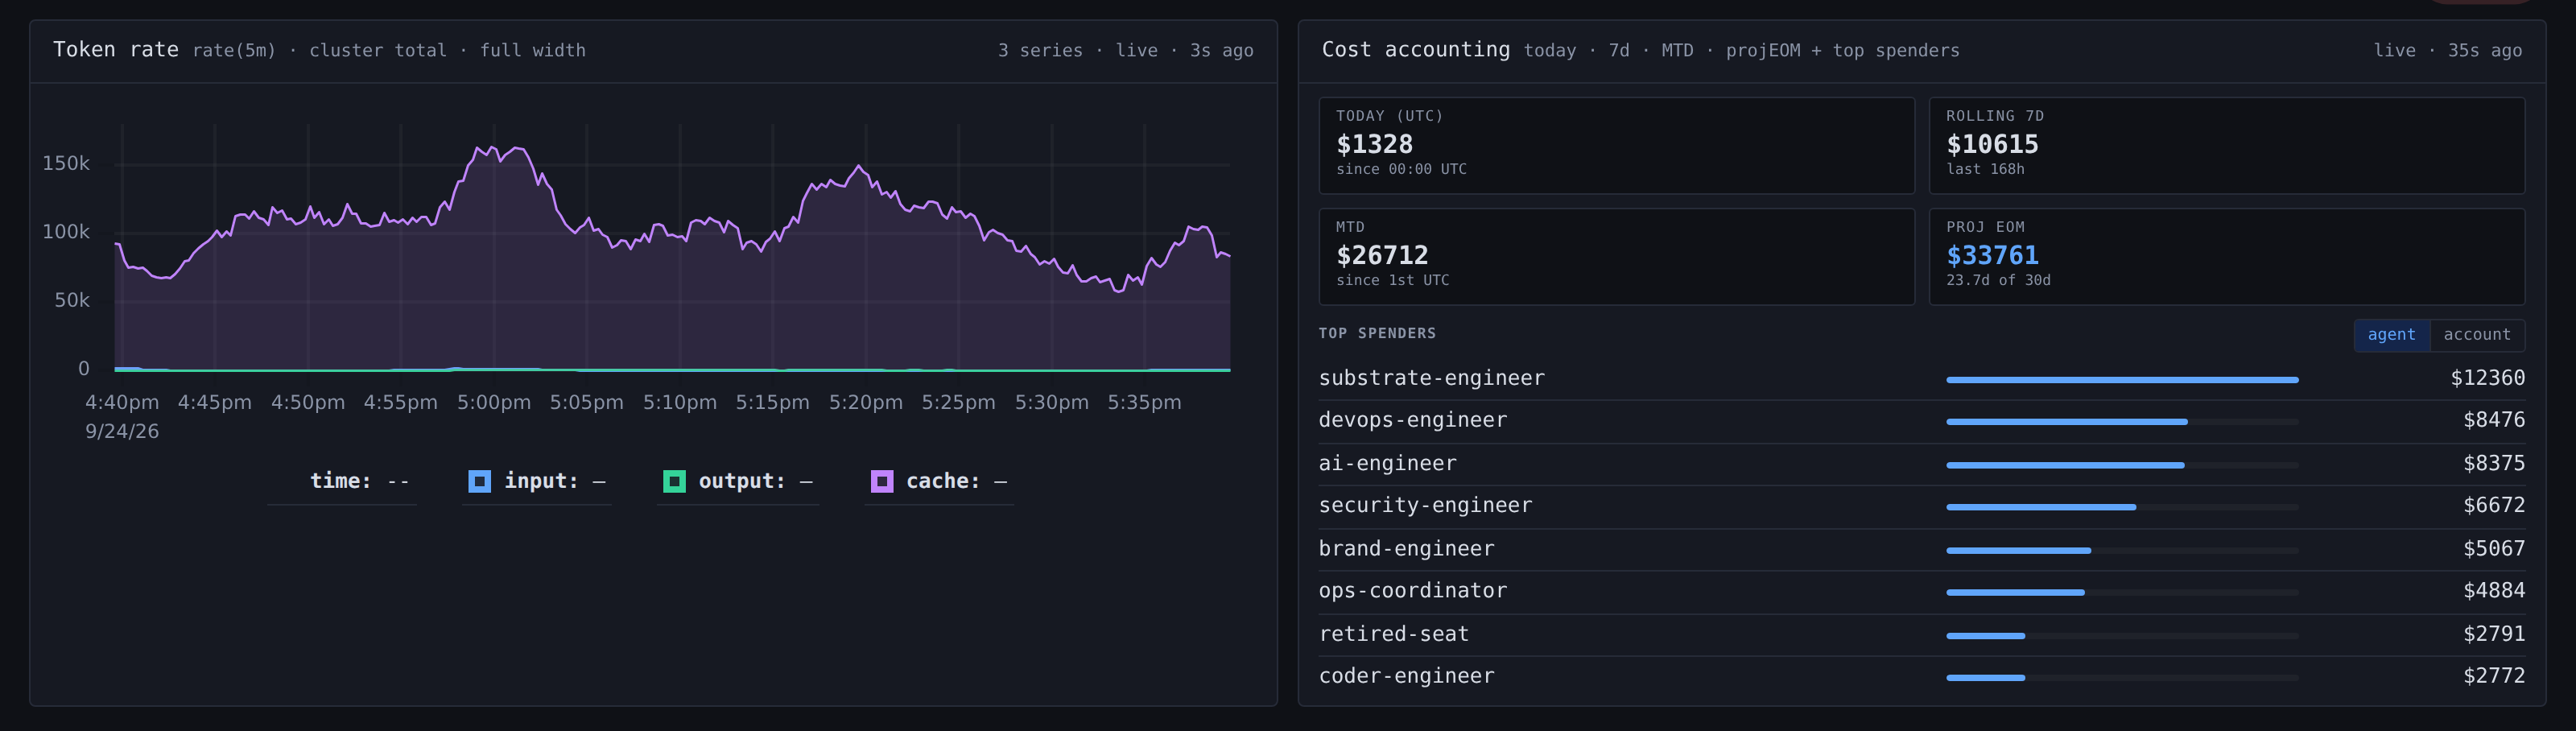
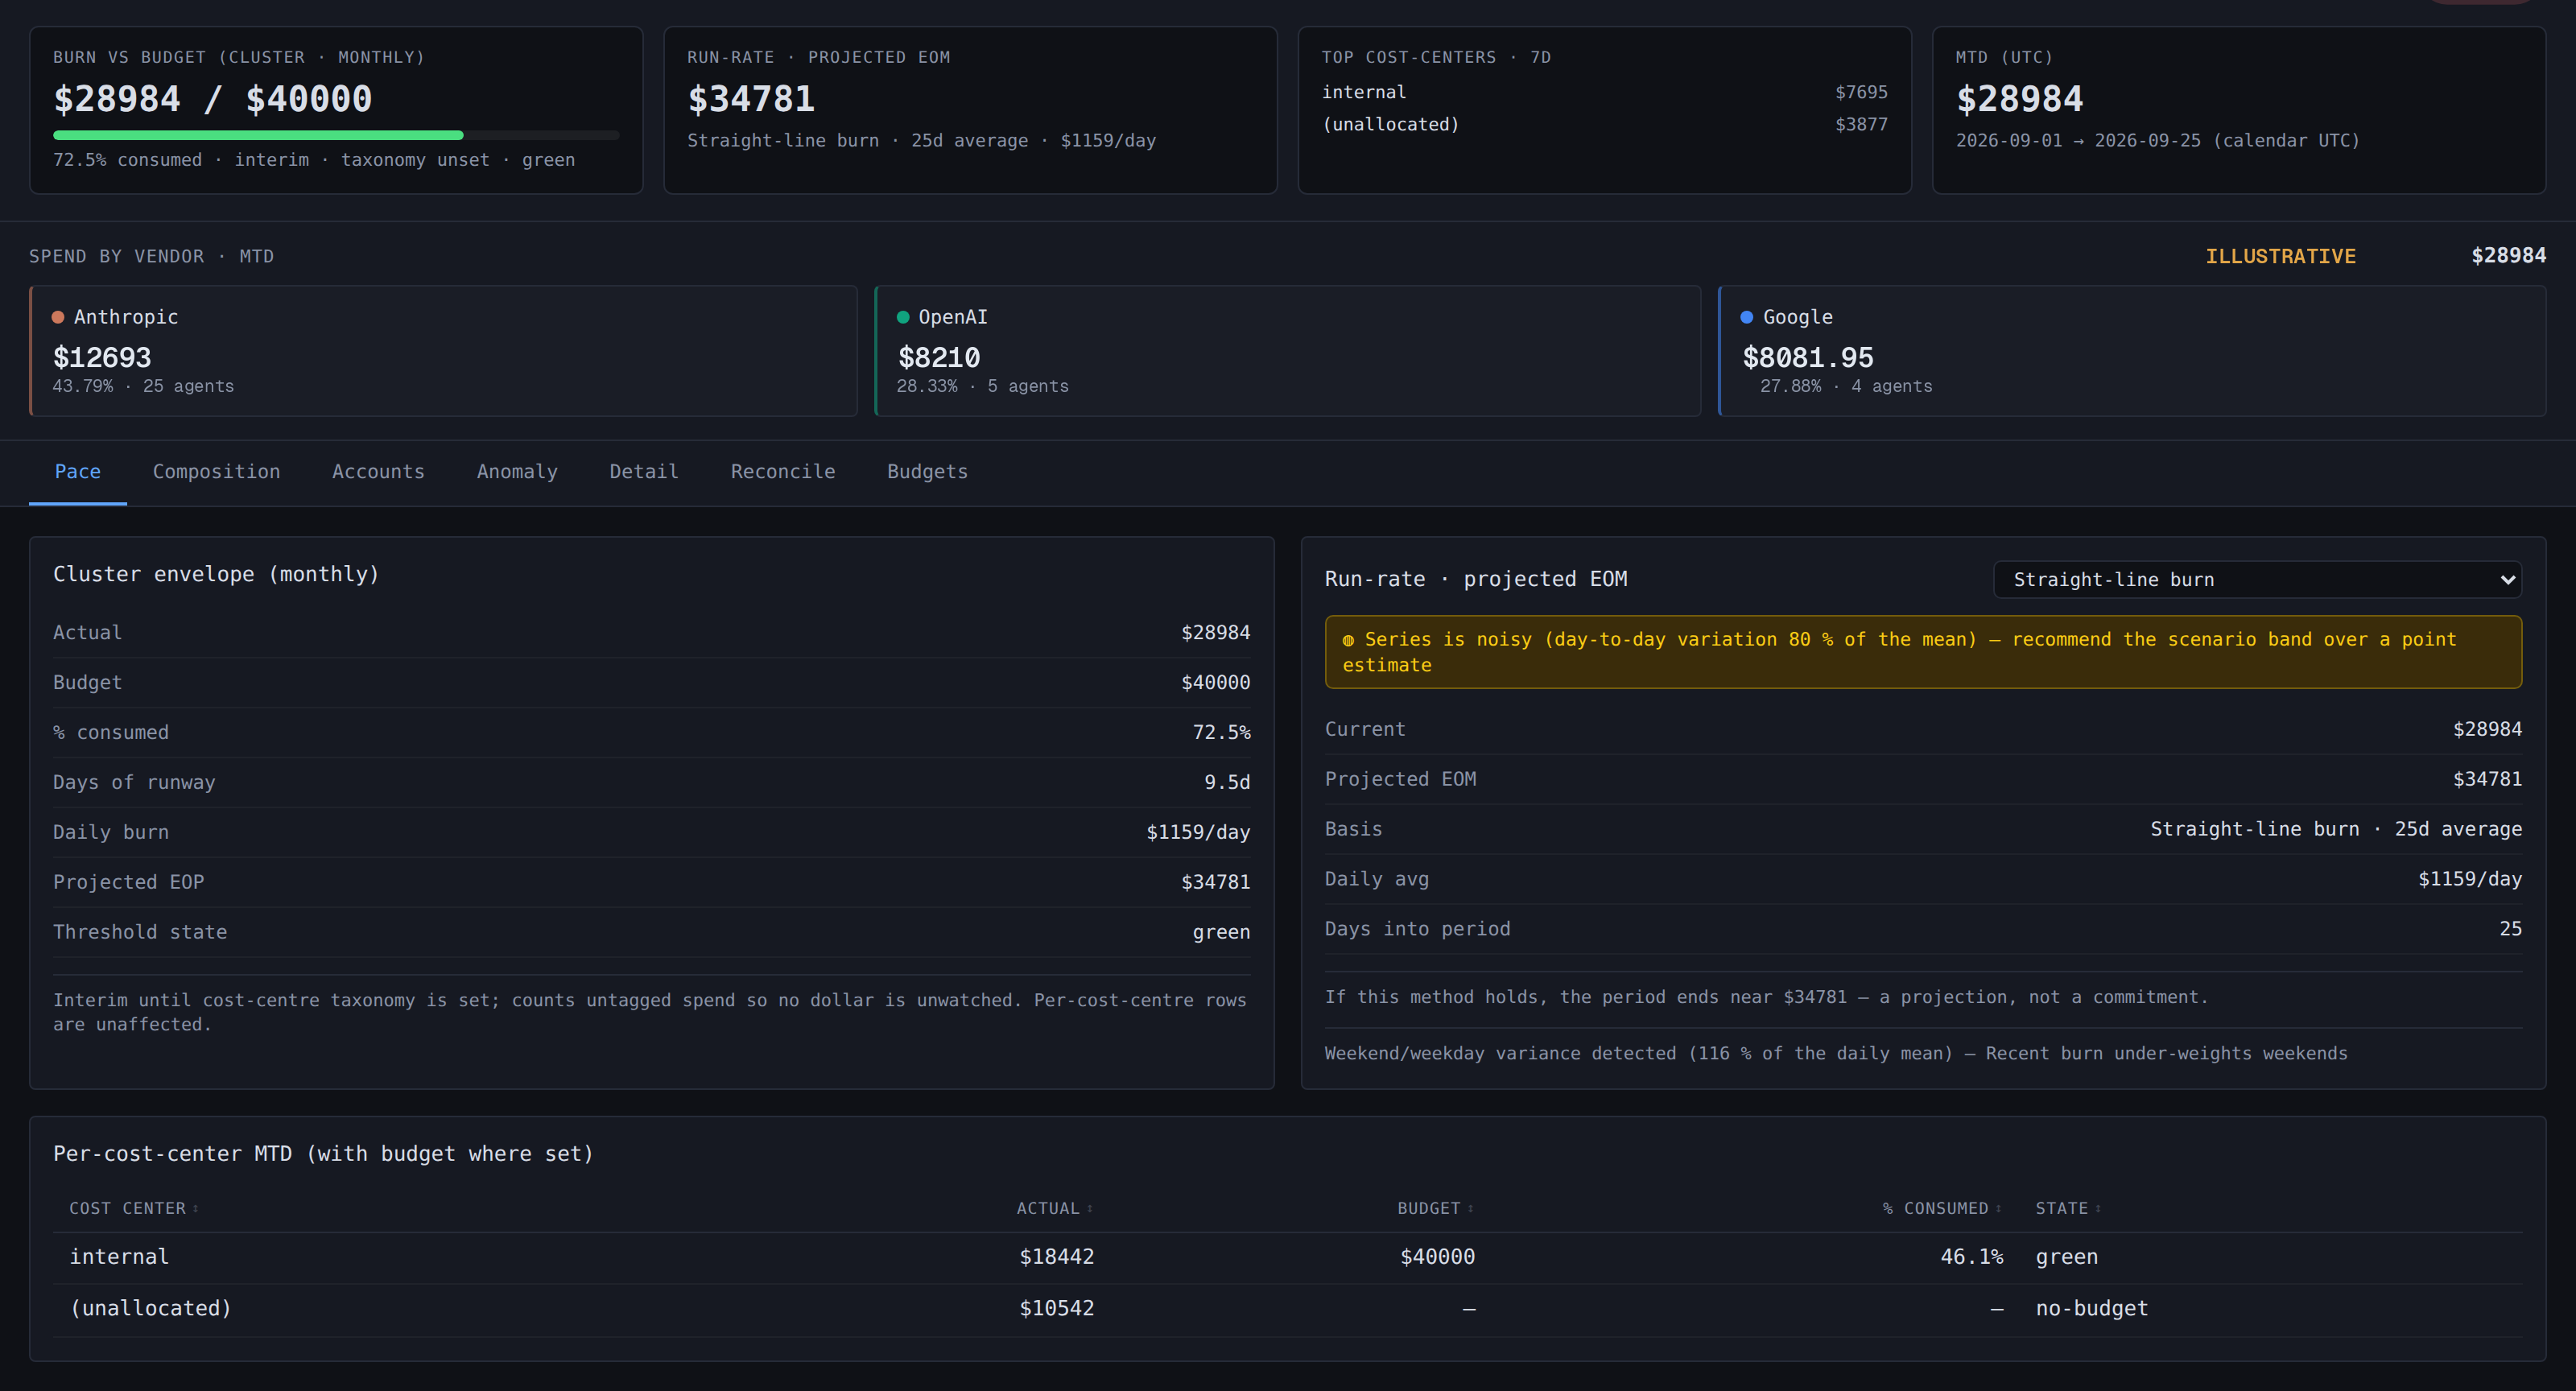
Plexus dashboard · token rate and cost
Two screens from the Plexus dashboard. The first shows how fast the fleet is spending tokens and which agents spent the most. The second tracks spend for the month against the budget you set, by vendor and by cost centre. Select either screenshot to open it full size.
§ 03 Harness Autonomy Tiers
Grant autonomy at a pace you can defend.
You do not have to grant full autonomy on day one. Your organization can start fully supervised and advance as the audit trail earns trust.
§ 04 Operating record
We have run the layers beneath this since 2008. We still do, every day.
The operators behind Subnet345 built and ran the global cloud behind McAfee's Global Threat Intelligence, the real-time service answering billions of queries a day; one of them is a named co-inventor on two U.S. patents in network-traffic prioritization.
Today that same practice runs a multi-agent operation in daily production. We do not demo the discipline. We run on the substrate ourselves.
The coordination core the product is built around is open source and MIT-licensed. See our open source →
§ 05 Industries
Industries where AI has to be right.
See the full industry overview on the industries page →
Pre-launch
Deploying agents into production? Request a demo.
See Plexus record and audit what your AI agents do, inside your own boundary.
Request a demo →